
TokenBlog
Model releases, pricing breakdowns, and practical guides for developers.
Muse Spark Open pricing: five hosts, one price, and it is closed Muse Spark 1.3's card for…
Meta released Muse Spark Open's 816B weights on October 15 and kept it off its own API. Together, Fireworks, Baseten, Modal and Nebius all sell it at $1.25 in and $4.25 out, the closed 1.3's rate to…
GPT-4o and GPT-4.1 retire January 14, GPT-4.1 nano in a week: what moving to GPT-6 Luna…
OpenAI's October 14 notice shuts down five GPT-4o and GPT-4.1 snapshots on January 14, 2027 and points them all at GPT-6 Luna. A $700 GPT-4o…
7 min read
GPT-6.1 Sol Ultrafast pricing: $12 in, $60 out, and more per token than GPT-6 Astra
OpenAI's Ultrafast tier for GPT-6.1 Sol went live on October 8 at exactly 6x Standard on every line, cache reads and the long-context step…
6 min read
OpenAI priced its Decisions API at $0.10 in and nothing out, and Microsoft priced…
GPT-6 Luna Decisions went into beta on October 6 at $0.10 per million input tokens with no output or cache charges. Microsoft-Decision-1…
6 min read
Meta priced Muse Wonder at Claude Opus 5.5's $4 and $20 to the cent. Opus on high effort…
Muse Wonder bills $4 input, $0.20 cached and $20 output on the Meta Model API, the same three numbers as Opus 5.5, with no batch tier and no…
6 min read
Nano Banana 2.1 halves what Google charges for a 1K or 2K image and triples what it…
Google's new image model bills $0.0336 at 1K, $0.0504 at 2K and $0.113 at 4K, against Nano Banana 2's $0.067, $0.101 and $0.151. Input went…
6 min read
Gemini 2.5 doesn't shut down on October 16. Vertex retires it on October 20, the Gemini…
Google's two consoles now disagree about the same three models. Vertex retires 2.5 Pro, Flash and Flash-Lite on October 20; the Gemini API…
6 min read
Mistral Large 4 launched at half price and Mistral hasn't said when the sale ends. At…
Mistral's docs show Large 4 at $0.68 input and $2.09 output with the $1.36/$4.18 list price struck through and no end date. We price a…
7 min read
Claude Haiku 5.5 bills GPT-6 Luna's $0.10 and $0.50 to the cent. One token past 100,000…
Anthropic cut Haiku 90% on October 7 and landed exactly on Luna's rate card, cache read included. Below 100K tokens the two bill…
7 min read
Eleven decision models launched in 17 days and none of them bill for output. On a…
Jev, Clef, d1, Perplexity's Decider and seven more return probabilities instead of text and charge input only, from $0.04 to $0.24 per…
7 min read
Grok 4.7 and MiMo-V2.6-Pro tie at 46 on Artificial Analysis. Grok's output price is 6.9x…
Grok 4.7 kept Grok 4.6's $2/$6 card. Xiaomi's open-weight MiMo-V2.6-Pro lists at $0.435/$0.87 with cache hits at $0.0036. Both score 46 on…
6 min read
Alibaba charges double for Prime on Qwen3.8 Max and GLM-5.3. On Qwen it buys 1.6x to 1.9x…
Alibaba's new Prime mode sells Qwen3.8 Max at $4/$12 and GLM-5.3 at $2.80/$8.80, twice the standard cards, for a promised 1.5x to 2x…
6 min read
GPT-6 Luna's tokens cost a twentieth of GPT-6.1 Sol's. On Artificial Analysis a finished…
GPT-6 Luna lists at $0.10 in, $0.01 cached and $0.50 out, half of GPT-5.6 Luna and 1/20th of GPT-6.1 Sol. Per task the picture changes: Luna…
6 min read
Gemini 4 Argon launches on GPT-6.1 Sol's rate card and is scheduled to move to Claude Opus…
Google priced Gemini 4 Argon at $2 in, $0.10 cached and $10 out for an introductory period with no end date, then $4, $0.20 and $20. The…
7 min read
GPT-6.1 Sol changed one number on GPT-6 Sol's rate card, cached input, from $0.20 to…
OpenAI shipped GPT-6.1 Sol at DevDay on September 29 at $2 in and $10 out, with cached input halved to $0.10 on every tier. On agent loops…
7 min read
Claude Sonnet 5.5 kept Sonnet 5's $2 and $10. Of its five effort settings, one is ever the…
Sonnet 5.5 shipped September 28 on Sonnet 5's card to the cent: $2 in, $0.20 cache hit, $10 out, which is also GPT-6 Sol's. Anthropic says…
9 min read
Claude Opus 5.5 lists at exactly twice GPT-6 Sol. Run both flat out and Opus costs 5.6x as…
Anthropic and OpenAI shipped their new mid-price flagships about 90 minutes apart on September 22. Opus 5.5 is $4 in, $0.20 cache hit, $20…
10 min read
OpenAI put a price on GPT-Rosalind for the first time: $5, $0.50 and $25, which is Claude…
GPT-Rosalind ran for 172 days without a rate card. On September 8 the API changelog called it generally available through the trusted-access…
12 min read
Anthropic counted 189.9 million distillation exchanges across five Chinese labs and…
Anthropic's September 10 threat report gives five per-lab counts of 'exchanges observed' against Claude, over 151 million for Alibaba, 23…
13 min read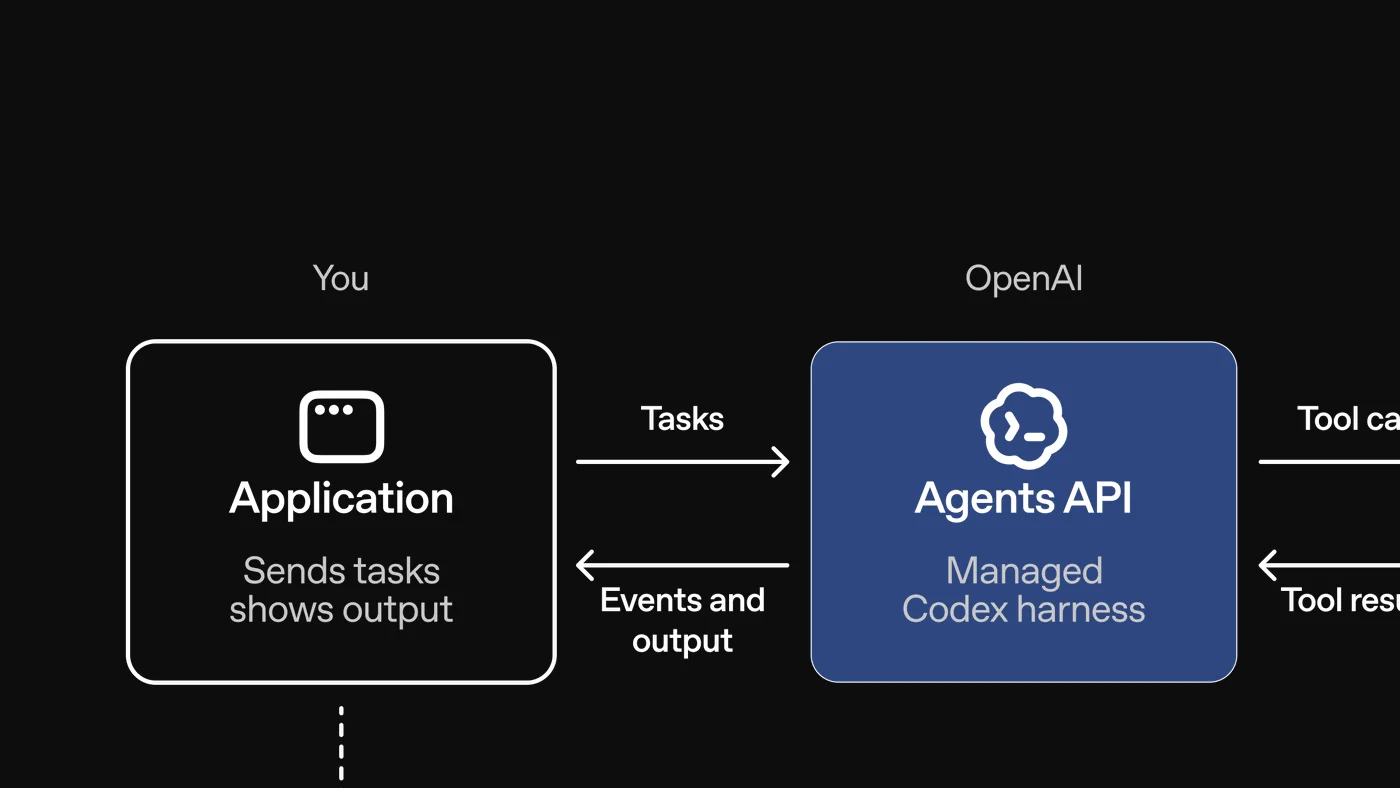
OpenAI says the Agents API has no additional fees, and it does not. The sandbox every…
The Agents API went into public beta on September 10 with one pricing sentence: 'you simply pay for the tokens and tools your agents use.'…
15 min read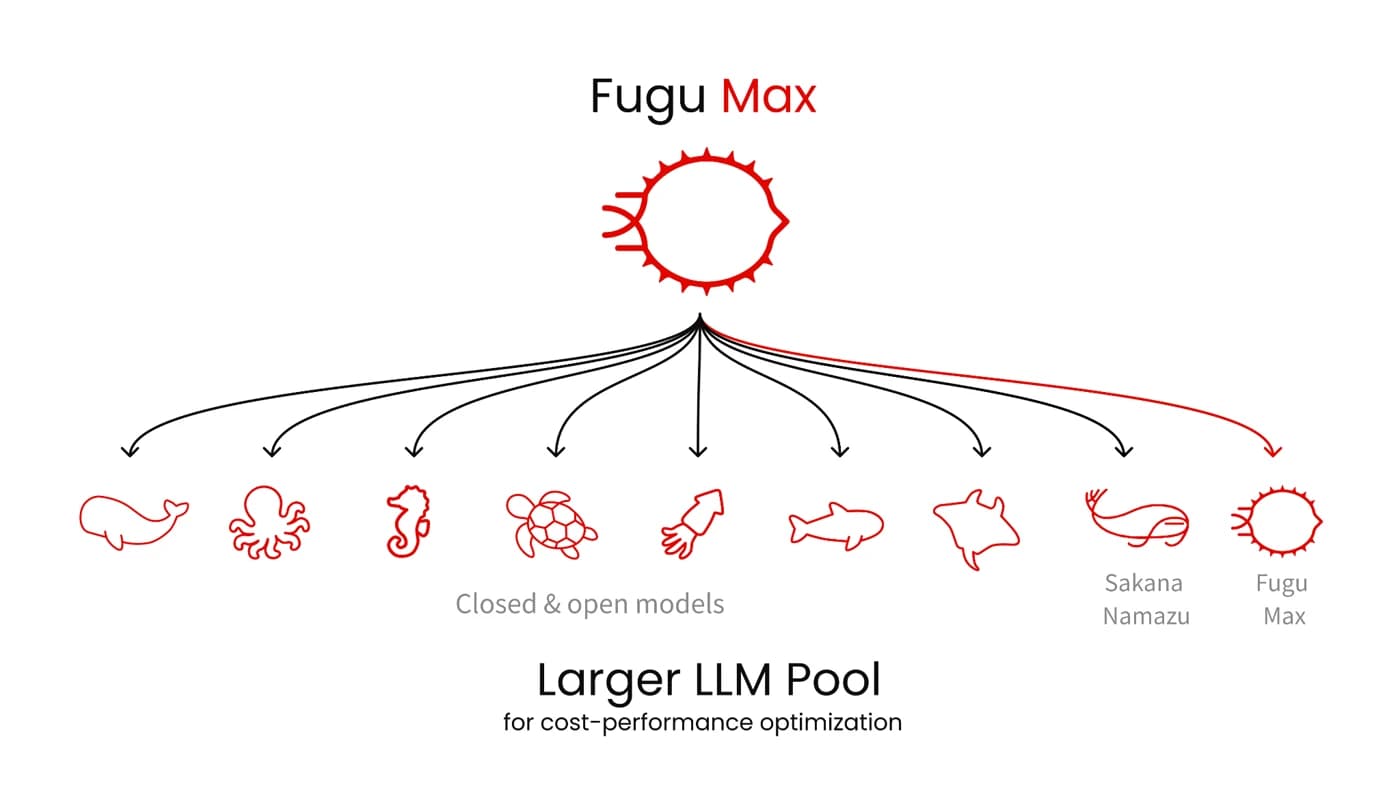
Sakana priced Fugu Max at $2 and $6, which is Qwen3.8 Max's card to the cent, and says the…
Fugu Max went on sale September 11 at $2.00 input, $6.00 output and $0.25 cached input per million tokens, flat to 1M context, as a new line…
14 min read
OpenAI priced GPT-Live-1 at $0.05 a minute, the number Vapi charges to host a voice agent…
GPT-Live-1 went generally available in the API on September 10 at $0.05 per minute of session, metered per second with no rounding, on the…
12 min read
DeepSeek cut Flash to $0.15 this morning and will bill its Pro tier at the same rate from…
Correction, September 12: DeepSeek withdrew the September 14 routing on September 11, 'in response to user demand', and deepseek-v4-pro…
13 min read
OpenAI shipped a new image model on the old model's rate card and moved every quality…
GPT Image 2.5 arrived on September 8 with five price lines identical to GPT Image 2, to the cent, on both the Sunburst and Flare snapshots…
12 min read
Every model measured across both rewrites of the industry's most-quoted leaderboard lost…
Artificial Analysis shipped Intelligence Index v4.2 on September 4 and v4.3 on September 7. Claude Fable 5.1 scored 65.65 before them and…
13 min read
At 07:00 UTC tomorrow the cheapest model we can price goes up 5.00x, and the number that…
Mercury 2.5 has been selling since August 31 at $0.04 and $0.15 per million tokens. On September 8 it becomes $0.20 and $0.75. The discount…
12 min read
Every comparison of an LLM against a document parser is run on input tokens. Input is the…
Cohere shipped Parse 5 on August 27 at $1.50 per 1,000 pages. AWS Textract charges $1.50 per 1,000 pages. Azure charges $1.50 and has since…
13 min read
Three labs shipped a security-gated model in three days. Anthropic published a full rate…
Claude Mythos 5.1 landed September 1, Gemini 3.8 Flash Cyber September 2, and OpenAI's $1 billion Daybreak commitment September 3. Three…
12 min read
GPT-6 Astra's rate card is Claude Fable 5's rate card, to the cent, on every line both…
OpenAI shipped GPT-6 Astra on September 3 at $10.00 per million input tokens, $1.00 cached, $12.50 for a cache write and $50.00 output…
13 min read
Gemini 3.8 Flash arrives on an introductory price that is not counted from its…
Google shipped its third Flash model in six weeks on September 2, at $0.75 per million input tokens and $3.75 per million output. Gemini 3.7…
12 min read
Claude Fable 5.1 charges what Fable 5 charged on every line of the rate card except one…
Anthropic shipped Fable 5.1 and Mythos 5.1 on September 1 and left almost the whole card alone: $10.00 input, $50.00 output, $12.50 and…
12 min read
Four companies sell Grok 4.6 and all four print $2.00 and $6.00. The whole difference…
xAI, Google, Amazon and Microsoft all list Grok 4.6 at $2.00 per million input tokens, $0.50 cached and $6.00 output. Copy those three…
11 min read
Tencent priced its new flagship at 6 yuan per million input tokens and printed $0.834 next…
Hy4 preview landed on Thursday at 06:09 UTC: 770B parameters with 49B active, a 1,048,576-token window, Apache 2.0 weights, and one seller…
12 min read
Eight AI API discounts expire on a published date between September 7 and January 1. Half…
Introductory pricing has become the normal way to launch a model, so a growing share of the rates in your spreadsheet are offers with a…
14 min read
Two models called Flash arrived five and a half hours apart yesterday. One of them looks…
Z.ai listed GLM-5.3-Flash at 13:59 UTC on August 26 and Alibaba listed Qwen3.8-Flash at 19:37. Every tracker shows the first at $0.075 per…
12 min read
Three models charge exactly $2.00 per million input tokens. The same 4K screenshot costs…
Every pricing page quotes dollars per million tokens and almost none of them say how many tokens a picture is. We collected the counting…
12 min read
Localizing a million characters into four languages costs $0.48 on Tencent's new…
Tencent put its Hy-MT2 translation family on a metered API last week, three months after releasing the weights under Apache 2.0. We counted…
11 min read
Ox Alpha bills $0 today. Its listing carries a setting that only two of OpenRouter's 422…
An unattributed model appeared on OpenRouter on August 20 at 20:04 UTC priced at nothing, and the weekend went to guessing which lab owns…
11 min read
OpenAI cut GPT-5.6 Sol to exactly 0.8 times Claude Opus 5 on every line it sells. Azure…
OpenAI dropped GPT-5.6 Sol on August 21 under a headline of "over 20%", which undersells it on output and oversells it as permanent. Input…
11 min read
GLM-5.3 bills the same $1.40 and $4.40 that GLM-5.2 and GLM-5.1 billed, and finishing a…
Z.ai put a per-token price on GLM-5.3 on August 18, four days after the model arrived reachable only through a subscription, and the price…
11 min read
Claude's new browser tool bills about 6,610 input tokens before it reads a word of your…
Anthropic made computer use generally available on August 19 and launched a browser tool beside it, publishing the token overhead for both…
11 min read
Bedrock sells GPT-5.6 Sol at exactly OpenAI's list price and also at 1.10x it. Which one…
AWS publishes five Bedrock model cards for GPT-5.6 and only three of them have a cheap row. Ordinary GPT-5.6 Sol carries three routing…
10 min read
Terminal-Bench 3.0 publishes what every run cost, which almost no other leaderboard does…
Agent leaderboards almost never tell you what the run cost. This one has a COST column and a TOKENS column next to the score, split per row…
11 min read
DeepSeek said the increase would be significant. It is 1.80x off-peak and 3.59x at peak…
At 16:00 UTC today DeepSeek's rate card split in two. V4-Flash goes from a flat $0.14 and $0.28 per million tokens to $0.22 and $0.66 for…
10 min read
Grok 4.6 costs exactly what Grok 4.5 costs on input, on output, and at the cliff. The only…
xAI shipped Grok 4.6 on August 12 and put it on the rate card of the model it succeeds. Input $2.00, output $6.00, a 500,000 token window…
11 min read
Google cut Gemini 3.6 Flash in half on Thursday and launched Gemini 3.7 Flash at the same…
Gemini 3.7 Flash went GA on August 13 at $0.75 input and $3.75 output per million tokens, and the coverage all repeated the same framing…
12 min read
Meta gave Muse Glimmer's weights away yesterday and exactly one company sells it. $0.35…
Meta shipped a 30B dense model under Apache 2.0 on August 10, its first open weights in more than a year, and named twelve launch partners…
11 min read
Imagen 4 stops answering on August 17. Google's pages send you to two different…
Three endpoints go dark next Monday, and the retirement changes the billing unit rather than just the number. Imagen 4 sold an image for a…
13 min read
On August 1 we wrote that nobody was going to bill you $20 per million input tokens. Four…
OpenAI's changelog for August 5 is one sentence long and mentions no price: Fast mode now supports long-context requests for GPT-5.6 Sol…
11 min read
Anthropic will now stop an agent session at a number you choose, written in whole cents as…
Session budgets shipped for Claude Managed Agents on August 7. Set budget.max_list_cost.amount to "2500" and the session stops at $25, which…
12 min read
DeepSeek says a significant price increase is coming and will not say how significant. We…
A three-sentence notice went up on DeepSeek's pricing page on August 6, as footnote number two under the rate table. No percentage, no…
11 min read
Ling-3.0-flash sells for $0.021, $0.06 and $0.075 per million input tokens right now. Same…
Ant Group put a 124B MoE on the API on July 23 and did not open the weights until August 2, one day before the free trial expired. What…
12 min read
Meta will cut your API bill 22x for permission to train on your prompts. The rate that…
Muse Spark 1.2 shipped on August 5 with a second model ID beside it. muse-spark-1.2-contributor bills $0.10 input, $0.002 cached input and…
11 min read
grok-voice-latest moved to Think Fast 2.0 this morning, so unchanged code now bills 60%…
xAI repointed the grok-voice-latest alias today, taking anyone who used it from $0.05 a minute of audio to $0.08. That is $3.00 an hour…
13 min read
Qwen3.8-Max prices output 60% under Kimi K3. On the same benchmark suite the bill came in…
Alibaba took its 2.4T-parameter flagship to general availability on August 3 and every gateway now quotes $2 input and $6 output per…
11 min read
Qwen3.7 Flash lists at $0.03 a million. One token past 32K, the identical request bills…
Alibaba priced its newest cheap tier at $0.03 input and $0.13 output, which is the lowest sticker on any 1M-context model you can call…
10 min read
DeepSeek kept the price at $0.14 and added ten index points. Eleven models now tie on…
On July 31 DeepSeek pushed a new build behind an endpoint that already existed, kept the model ID, kept the architecture and kept every…
10 min read
OpenAI and Anthropic both charge exactly double for speed. One of them tells you how much…
Latency stopped being a capacity commitment and became a per-request purchase in the space of eight days. Anthropic closed Priority Tier to…
11 min read
OpenAI cut GPT-5.6 Luna by 80% and left Sol untouched. That is a 25x spread inside one…
On July 30 Luna went from $1.00 and $6.00 per million tokens to $0.20 and $1.20, an identical 80% off input, output and cached input. Terra…
9 min read
Anthropic says one cryptographic attack cost it about $100,000 in API time. Its own price…
Labs almost never publish what a task cost them. On July 28 Anthropic did, twice: roughly $100,000 per result, one billion output tokens…
9 min read
Anthropic cancelled the Claude Sonnet 5 price increase. $2 and $10 are the standard rates…
Updated August 16. Anthropic has withdrawn the increase it had scheduled for September 1: its pricing docs now state that the $2 and $10…
10 min read
Kimi K3's weights went up for free on Monday and every host still matches Moonshot's…
Open weights normally start a price war. Moonshot published the full Kimi K3 checkpoint on July 27 and ten providers now serve it, none of…
11 min read
Poolside is selling a 118B coding model for 10 cents in and 20 cents out. It also…
Laguna S 2.1 shipped July 21 with open weights and a rate card of $0.10 input and $0.20 output per million tokens, a fiftieth of GPT-5.6 Sol…
10 min read
Google's Lite tier keeps getting less lite. A year of releases took Flash-Lite output from…
Gemini 3.5 Flash-Lite shipped July 21 at $0.30 input and $2.50 output per million tokens, against $0.25 and $1.50 for the model it replaces…
9 min read
DeepSeek switched off deepseek-chat and deepseek-reasoner yesterday. The rename is one…
On July 24 at 15:59 UTC, DeepSeek retired its two oldest API model names, and requests to deepseek-chat and deepseek-reasoner now fail…
8 min read
Anthropic shipped Opus 5 at the same $5/$25 it charged for 4.8. The story is what that…
Claude Opus 5 landed July 24 with a rate card copied from Opus 4.8, $5 input and $25 output per million tokens, unchanged for a fourth Opus…
8 min read
Every big lab now ships a dedicated coding model. Their output prices run from $0.80 to…
Once you filter the July 2026 rate cards down to the models sold specifically for coding agents, the label stops meaning anything about…
8 min read
Claude Opus 4.8 just slipped off the LLM value frontier. A $3 model scores higher on the…
Rank every current model by Artificial Analysis's Intelligence Index and by what it actually costs to run that eval suite, and the July 2026…
9 min read
Alibaba says Qwen3.8 Max is the world's second-best model. It won't publish a benchmark…
Qwen3.8 Max previewed July 19 at WAIC Shanghai, two days after Kimi K3 went open weights, and Alibaba called it second only to Claude Fable…
7 min read
Google cut Gemini Flash's output price and taught it to say less. Do both at once and the…
Gemini 3.6 Flash shipped July 21 with output dropped from $9 to $7.50 per million and a claim it uses 17% fewer output tokens than 3.5…
8 min read
Mira Murati's lab open-sourced a frontier-class model. The strange part is how hard it is…
Inkling landed July 15 as the first open model from Thinking Machines: 975B parameters, Apache 2.0, and the top Artificial Analysis score of…
7 min read
Every major LLM API now knocks about 90% off the tokens you cache. The bill you don't see…
Cached input reads have quietly standardized near a tenth of the base price across OpenAI, Anthropic, and Google, and DeepSeek goes further…
8 min read
American teams now route a third of their tokens to Chinese models to save money. The plot…
US companies have made up more than 30% of Chinese-model token traffic on OpenRouter every week since February, and the reason is the…
8 min read
For two years the story out of China was that prices only fall. Moonshot just tripled its…
Kimi K3 lists at $3/$15 per million tokens against K2.6's $0.95/$4.00, a 3.16x input and 3.75x output increase under three months apart. An…
9 min read
A Kuaishou team just priced 94 percent of Opus 4.8's coding score at a seventh of the…
Kwaipilot's KAT-Coder-Pro v2.5 lists at $0.74/$2.96 per million tokens, with a cheaper Air tier at $0.15/$0.60. On SWE-Bench Pro it scores…
8 min read
Claude runs five times apart from its cheapest tier to its priciest. The capability gap is…
Anthropic's lineup runs $1/$5 for Haiku 4.5, $3/$15 for Sonnet 5, and $5/$25 for Opus 4.8 - a clean 5x from floor to ceiling. Priced by the…
8 min read
Grok 4.5 sells the cheapest token, Fable 5 sells the smartest one, and neither is the…
GPT-5.6 Sol ($5/$30), Claude Fable 5 ($10/$50), and Grok 4.5 ($2/$6) span five times over on price but bunch near the top on capability…
9 min read
Claude Fable 5 is back on subscriptions, but not the way it left. Included access is gone…
Anthropic pulled Fable 5 from Pro, Max, and Team plans in June on capacity, then brought it back behind metered usage credits at its full…
8 min read
The first model Meta ever charged for is priced to win agent work, not coding. At $1.25…
Meta opened its first paid API on July 9 with Muse Spark 1.1 at $1.25 input and $4.25 output per million tokens, roughly a quarter of what…
8 min read
Grok 4.5 undercuts Opus 4.8 by two-thirds and burns fewer tokens getting there. The…
xAI shipped Grok 4.5 on July 8 at $2 input and $6 output per million tokens. Against Opus 4.8, Fable 5, and GPT-5.6 Sol it runs 68 to 84…
8 min read
Meituan's LongCat-2.0 costs 75 cents a million and tops the open coder benchmarks. You…
LongCat-2.0 went public June 30 at $0.75 input and $2.95 output per million tokens, with a launch promo cutting that to $0.30/$1.20. It…
8 min read
OpenAI built a chip to make inference cheaper. That is a different thing from making your…
Jalapeño, OpenAI's first custom inference processor with Broadcom, landed June 24 alongside Google's Ironwood TPUs and AWS Trainium 3. The…
8 min read
OpenAI split GPT-5.6 into three tiers and priced the flagship exactly where GPT-5.5…
GPT-5.6 arrived June 26 as Sol, Terra, and Luna at $5/$30, $2.50/$15, and $1/$6 per million tokens. Sol, the flagship, costs to the cent…
7 min read
Claude Sonnet 5 lands level with Opus 4.8 on an independent benchmark and asks 60% less…
Anthropic shipped Sonnet 5 on June 30 at $2/$10 per million tokens, an introductory rate that runs through August 31 before rising to…
8 min read
DeepSeek V4 will charge double during its busiest hours. Whether you ever pay the…
From the mid-July V4 launch, DeepSeek doubles its API rates during two daily windows - 9am to 12pm and 2pm to 6pm Beijing time. It is the…
7 min read
The US gated its two newest flagships in a day. The models you can still call are open…
On June 26 the US held OpenAI's GPT-5.6 to government-approved partners and let Anthropic re-open Claude Mythos 5 to a short list of trusted…
8 min read
Doubao 2.1 Pro undercuts Claude Opus by 80%. The price is real, but it is quoted in yuan…
ByteDance launched Seed 2.1 (Doubao 2.1) on June 24 with Pro and Turbo tiers priced only in yuan: roughly $0.88 input and $4.41 output per…
7 min read
Nex-N2-Pro scores like a frontier coder and bills like a budget one. The free weights are…
A little-known lab, Nex AGI, shipped a 397B open-weight model that posts 80.8 on SWE-Bench Verified and costs about a tenth of GPT-5.5…
7 min read
Google promised Gemini 3.5 Pro in June. It is late, has no price, and no benchmarks.
Google teased Gemini 3.5 Pro at I/O on May 19 with a 2M context window and Deep Think, then went quiet. No rate card, no benchmark sheet…
7 min read
Claude won't bill you for a refusal. A fallback credit stops you paying twice.
Claude Fable 5 has been dark for twelve days, but the billing rules it shipped with outlast it. Anthropic does not charge you for a refused…
7 min read
Three frontier coders now cost under a dollar a million. The cheapest sticker is not the…
DeepSeek V4-Pro, Qwen3.7 Plus, and MiniMax M3 all undercut $0.60/M input. Sort by input price and Qwen wins; run an actual coding month and…
8 min read
GLM-5.2 costs a fifth of GPT-5.5 and says it codes better. One of those claims you can…
Z.ai's open-weight GLM-5.2 undercuts GPT-5.5 by roughly 5x per token and self-reports a coding-benchmark win on top. The price is on the…
7 min read
GPT-5.6 is probably days away. Here is what the leaks confirm and what your bill might do.
A gpt-5.6 ID leaked from OpenAI's own Codex backend, the chief scientist reportedly called it a meaningful improvement, and the release-date…
7 min read
Anthropic charges double and keeps winning. Now OpenAI might blink on price.
OpenAI and Anthropic filed to go public a week apart, then OpenAI was reported to be weighing token price cuts to slow Anthropic down. The…
7 min read
Claude Fable 5 lasted three days. Every alternative is cheaper.
Anthropic disabled Claude Fable 5 and Mythos 5 on June 12, 2026 under a US export-control order, three days after launch. Fable 5 was the…
7 min read
GLM 5.2 and Kimi K2.7 Code shipped five days apart. You still cannot benchmark one against…
Two Chinese labs put out open-weight coding models in the same week. Kimi K2.7 Code lists at $0.95/$4.00 per million tokens, GLM 5.2 at…
6 min read
GLM 5.2 has no token price and no benchmarks. The whole pitch is a $10 subscription.
Z.ai shipped GLM 5.2 on June 13 with a 1M-token context and a coding-first pitch, but no per-token API rate and not a single published…
7 min read
Claude Opus 4 retires today. Its replacement costs a third as much.
Claude Sonnet 4 and Opus 4 both retire June 15, 2026 on the Claude API, with calls failing hard after the cutoff. The Sonnet path is a flat…
7 min read
Step 3.7 Flash reads images and codes like a mid-tier model, for an eighth of Gemini…
StepFun shipped Step 3.7 Flash on May 29, an open-weight 198B vision MoE that lists at $0.20 in and $1.15 out per million tokens, roughly an…
8 min read
Kimi K2.7 Code costs exactly what K2.6 did. The rest you take on faith.
Moonshot shipped Kimi K2.7 Code on June 12 at $0.95 in and $4 out per million tokens, the same rate card as the model it replaces, with only…
7 min read
DiffusionGemma generates 4x faster than its own sibling and scores worse on every…
Google shipped DiffusionGemma 26B on June 10, an experimental open-weight model that writes text by denoising a canvas in parallel instead…
7 min read
Claude Fable 5 is the most expensive model Anthropic has ever shipped. For two weeks, it's…
Anthropic put its Mythos-class intelligence into general release on June 9 as Claude Fable 5, priced at $10 in, $50 out per million tokens…
8 min read
Xiaomi MiMo UltraSpeed charges 3x for 10x the speed. The catch is you can only rent it for…
Xiaomi opened a trial on June 9 for MiMo-V2.5-Pro UltraSpeed, a one-trillion-parameter model it claims runs past 1,000 tokens a second on…
8 min read
Gemma 4 12B has no API price. Google built it to run on your laptop, not on its meter.
Google shipped Gemma 4 12B on June 3, an encoder-free multimodal model that reads text, images, and audio, fits in 16GB of memory, and ships…
7 min read
Nemotron 3 Ultra has no list price. The same open weights run from $0.37 to $0.60 a…
NVIDIA shipped Nemotron 3 Ultra 550B on June 4, its biggest open model so far and the top-scoring US open-weights model on the Artificial…
8 min read
Microsoft's MAI-Code-1-Flash matches GPT-5.4 Mini to the cent, then claims a third fewer…
Microsoft shipped MAI-Code-1-Flash at Build on June 2 at $0.75 input and $4.50 output per million tokens, the exact rate as GPT-5.4 Mini…
8 min read
Qwen3.7 Plus costs a sixth of Max on input, and it can do the one thing Max can't: read…
Alibaba shipped Qwen3.7 Plus on June 1 at $0.40 input and $1.60 output per million tokens, a sixth of Qwen3.7 Max on input and under a…
8 min read
GPT-5.5 on priority costs 2.5x list. Here is what the speed actually buys.
OpenAI's priority serving tier bills GPT-5.5 at $12.50 input and $75 output per million, exactly 2.5x the standard rate, in exchange for a…
7 min read
MiniMax M3 claims GPT-5.5-class coding for a tenth of the price. The benchmarks are…
MiniMax M3 went live on June 1 at $0.60 input and $2.40 output per million tokens, with a 50% launch promo cutting it to $0.30/$1.20 for the…
8 min read
GPT-5.5 has a pricing cliff at 272K tokens. Cross it and the whole request bills double.
OpenAI prices GPT-5.5 at $5 input and $30 output per million tokens, but only until a request crosses 272K input tokens. Past that line, the…
8 min read
Cohere shipped a 218B Apache 2.0 model that runs on two H100s. The hosted rate matches…
Command A+ landed on May 20 as the first Cohere flagship under unrestricted Apache 2.0. The hosted API stays at $2.50 input and $10 output…
9 min read
Anthropic kept the Opus list price flat for the third release running. The headline is the…
Claude Opus 4.8 shipped on May 28 with standard pricing untouched at $5 input and $25 output per million tokens. The new Fast mode tier at…
8 min read
Qwen3.7 Max ties Opus 4.7 on intelligence and beats it on agentic coding, at half the…
Alibaba announced Qwen3.7 Max on May 20 at $2.50 input and $7.50 output per million tokens, against $5/$25 on Claude Opus 4.7 and $5/$30 on…
9 min read
Cursor Composer 2.5 lands one point behind Opus 4.7 on SWE-Bench and bills ten times less…
Cursor shipped its own coding model on May 18 with a week of double usage to soften the launch, and that promo ended around May 25. The…
9 min read
GPT-5.5 Pro lists at $30/$180 per million tokens, and it drops the cache discount that…
OpenAI's GPT-5.5 Pro costs six times the standard GPT-5.5 before the fine print, and the fine print is where it gets worse: Pro runs on the…
8 min read
Grok Build runs coding agents at $1 in, $2 out. The catch is that xAI published zero…
xAI shipped Grok Build, a terminal coding agent that reads your AGENTS.md and undercuts every rival on price: the grok-build-0.1 model…
7 min read
DeepSeek scrapped the May 31 price cliff. The 75% V4-Pro cut is the permanent rate now.
Three weeks ago DeepSeek's pricing page warned the V4-Pro discount expired May 31, with the rate stepping back up to $1.74/$3.48 per…
8 min read
Google cut AI Ultra to $100 at I/O. Now all three AI giants charge the exact same $20…
Google added a $100 AI Ultra tier at I/O on May 19 and dropped its old $250 plan to $200, snapping onto the exact $20/$100/$200 ladder…
8 min read
Your Claude subscription stops paying for agents on June 15. The SDK and claude -p move to…
Anthropic's email landed May 13: from June 15, 2026, the Claude Agent SDK, claude -p, GitHub Actions, and third-party harnesses like…
9 min read
Gemini 3.5 Flash costs 3x what Gemini 3 Flash did. Google priced it that way because it…
Google shipped Gemini 3.5 Flash on May 19 at I/O 2026 with a flat tripling of the Flash rate card: $1.50 input, $9 output, $0.15 cached per…
10 min read
xAI quietly swapped Grok 4.3's weights for Colossus-2-trained ones and switched on Agent…
Musk posted on May 18 that the latest Grok is now running on weights trained partly on Colossus 2, with Agent Mode unlocked for API…
9 min read
SubQ 1M-Preview shipped 12M tokens of context, no public rate card, and a $8-vs-$2,600…
Subquadratic launched SubQ on May 5 with $29M seed funding, a 12M-token research model, and a 1M production model. The headline claim is 95%…
10 min read
Qwen3.6 Max Preview is the first Qwen flagship Alibaba shipped closed. It took SWE-Bench…
Alibaba launched Qwen3.6 Max Preview on April 20 at $1.30 input and $7.80 output per million. The model unseated GLM-5.1 on SWE-Bench Pro…
11 min read
Anthropic is raising at $950B, up 2.5x in three months. Every recent move on the Claude…
Bloomberg, Sherwood, and Fortune confirmed May 11-13 that Anthropic is in talks to raise $30-50B at up to $950B valuation. That is 2.5x the…
10 min read
MiniMax M2.7 lists at $0.30 input, $1.20 output. The GDPval-AA score is the highest…
MiniMax M2.7 ships at $0.30/$1.20 per million on OpenRouter and MiniMax direct, with a ~$0.06 cached input tier. The 1495 GDPval-AA ELO is…
11 min read
Qwen3 Coder Next is still $0.11 per million input. Kimi K2.6 costs 7x more, GPT-5.5 costs…
Three months after release, Qwen3 Coder Next sits at $0.11/$0.80 per million on OpenRouter, $0.30/$1.50 on Alibaba DashScope, and Apache…
10 min read
Mercury 2 outputs at 788 tokens per second for $0.75 per million. The diffusion math turns…
Inception Labs' Mercury 2 is the first diffusion-based reasoning LLM. It ships at $0.25 input / $0.75 output per million, measured at 788…
11 min read
OpenAI's three new voice models price three different ways. Here is what an hour actually…
GPT-Realtime-2 bills per million tokens ($32/$64 audio, $0.40 cached). Realtime-Translate is $0.034/min flat. The new Whisper costs…
10 min read
Tencent's Hunyuan HY3 Preview is the cheapest frontier-class model, and it's 14 points…
Two prices: $0.066/M on OpenRouter, $0.17/M on Tencent Cloud direct. SWE-Bench Verified 74.4%, against GPT-5.5 at 88.7 and Opus 4.7 at 87.6…
9 min read
GPT-5.5 vs Opus 4.7 vs Gemini 3.1 Pro: the cheapest one depends entirely on whether you…
On a 50K-token request, Gemini 3.1 Pro is cheapest at $0.22, Opus 4.7 next at $0.50, GPT-5.5 last at $0.55. Past 200K, Gemini steps tier…
10 min read
DeepSeek V4-Pro's 75% promo ends May 31. After that, the price is 4x what most people are…
Every V4-Pro article since April 24 has been citing the launch promo, not the steady-state rate. DeepSeek's official page now puts the…
9 min read
GLM-4.7-flash sits at $0.07 input on AWS Bedrock and Vertex. Most coverage skipped this…
While GLM-5.1 ate every Z.ai headline, GLM-4.7-flash quietly stabilized across AWS Bedrock, Vertex AI, Cerebras, Together, and OpenRouter at…
8 min read
Mistral Medium 3.5 charges 17x more than DeepSeek V4 Flash and loses the only benchmark…
Mistral shipped Medium 3.5 on April 29 at $1.50 / $7.50 per million tokens with two published benchmark numbers. DeepSeek V4 Flash sits at…
9 min read
Three weeks of Opus 4.7 bills are in. The tokenizer change costs an extra 25 to 37 percent…
Anthropic kept Opus 4.7 at $5/$25 per million tokens but swapped the tokenizer underneath. Three weeks of production data from Finout…
10 min read
GPT-5.5 doubled the per-token price. The 40% efficiency claim does not get OpenAI back to…
OpenAI shipped GPT-5.5 at exactly 2x GPT-5.4 pricing and pitched it as a wash because the model uses fewer tokens. The 40% figure traces to…
10 min read
GLM-5.1 took SWE-Bench Pro at $1.40/M input. The catch is the small print, not the price.
Z.ai shipped a 754B MoE on April 7 that briefly held SWE-Bench Pro at 58.4 - above GPT-5.4 and Opus 4.6 - while charging less than a third…
8 min read
Grok 4.3 quietly cut prices 40-60%, then shipped a voice cloner. The pricing math is now…
xAI shipped Grok 4.3 at $1.25/$2.50 per million tokens with a 1M context, 192 tok/s output, and a Custom Voices API. Here is the pricing…
9 min read
DeepSeek V4-Flash redrew the budget LLM tier. Here is where Haiku 4.5, GPT-5.4 Nano, and…
DeepSeek V4-Flash at $0.14/$0.28 dropped the cheap-tier price floor by 4.5x on output. Eight days in, here is what the four budget-tier…
9 min read
Qwen3-Next-Thinking: the cheapest reasoning model under $1/M output
An 80B-param MoE that activates 3B per token, scores 87.8 on AIME25, and costs $0.0975/$0.78 per million tokens. The cheapest…
8 min read
OpenAI on AWS Bedrock: what it costs and what actually changed
Microsoft's exclusivity ended April 27. AWS had OpenAI models on Bedrock within 24 hours. GPT-5.4 is limited preview with no published…
7 min read
GitHub Copilot goes metered: what developers will actually pay per 1M tokens
GitHub drops premium request units and switches to AI Credits on June 1, 2026. Code completions stay free. Everything else - chat, agents…
8 min read
DeepSeek V4 vs GPT-5.5 vs Claude Opus 4.7: what three frontier models actually cost
Three major releases in two weeks. DeepSeek V4-Pro at launch discount is 11x cheaper on input than GPT-5.5 and Claude Opus 4.7. Here's the…
9 min read
Gemini Deep Research: what each AI research report actually costs
Google launched the Deep Research API on April 21. The official estimate is $1-3 per task - accurate, but it bakes in 50-70% cache hits and…
8 min read
Kimi K2.6: the fastest model in the top 5, at the lowest price
Released April 20, Kimi K2.6 scores 54 on the AA Intelligence Index - 3 points behind the frontier, but $1.71/1M blended and 134…
7 min read
Claude Code vs OpenAI Codex: which coding agent actually costs less in 2026?
OpenAI updated Codex on April 17 with computer use and 90+ plugins. We ran the API numbers across three usage tiers - Codex's container fees…
9 min read
Voice AI APIs in 2026: what Gemini TTS, Voxtral TTS, and OpenAI TTS actually cost per hour
Per-token pricing makes TTS costs hard to reason about. We converted Gemini 3.1 Flash TTS, Mistral Voxtral TTS, OpenAI TTS-1, and ElevenLabs…
7 min read
Gemini 3 Flash: $0.50 per million tokens, thinking on by default, and it actually beats…
Google launched Gemini 3 Flash preview in December 2025 at $0.50 input / $3.00 output. The catch: thinking is on by default and thinking…
7 min read
Tokenmaxxing can inflate your LLM API bill by 10x. On Gemini and GPT-5.4, it's worse.
The term went viral this week for a practice developers have been doing forever: stuffing prompts with as much context as possible. Two…
7 min read
Claude Opus 4.7: $5 per million tokens - and what that actually means now
Released April 16. The per-token rate is unchanged from Opus 4.6. But the new tokenizer can use up to 35% more tokens for the same code or…
8 min read
Claude Code Routines: what each automated run actually costs
Routines launched April 14, 2026 as a research preview. They run Claude Code sessions on Anthropic's servers -- scheduled…
7 min read
GPT-5.4 computer use: what a real agent task actually costs
Computer use sessions aren't like standard API calls. Screenshots accumulate with conversation history on every turn, GPT-5.4 has a 272K…
8 min read
DeepSeek V4: $0.30 per million tokens for a 1 trillion parameter model
DeepSeek V4 is not out yet but every major pricing tracker has landed on $0.30 per million input tokens. The leaked specs show 1M context…
8 min read
Chatbot Arena April 2026: Claude leads everything, Grok 4.20 has the cheapest output
The April 2026 LMSYS Chatbot Arena leaderboard has Claude Opus 4.6 Thinking at Elo 1504, holding #1 across every major category. Muse Spark…
7 min read
OpenAI's new $100 ChatGPT Pro: what you actually get on Codex, and when the API wins…
OpenAI added a new tier on April 9, priced to match Anthropic's Claude Max. It's not a price cut on the $200 plan - it's a new slot below…
7 min read
GPT-5.5 "Spud": release date, pricing forecast, and what we actually know right now
OpenAI finished pretraining on March 24. Polymarket gives it 78% odds of shipping by April 30. Here's everything confirmed, the signal…
7 min read
LLM API pricing in April 2026: from $0.05 to $125 per million tokens
The spread between the cheapest and most expensive LLM APIs is now 2,500x on output tokens. Every major model, every tier, and where the…
9 min read
Meta Muse Spark: no API pricing, no open weights, and one area where it's best in the…
Meta's first proprietary model landed April 8 with benchmarks but no public API. Fourth overall on the Artificial Analysis Intelligence…
8 min read
Project Glasswing and Claude Mythos Preview: the AI that found a 27-year-old bug for under…
On April 7, Anthropic officially announced Project Glasswing - a coalition of 52+ organizations with exclusive access to Claude Mythos…
9 min read
Is Claude Code getting worse? The data says something did change on March 8.
AMD's Senior Director of AI published 6,852 session logs showing Claude's thinking depth dropped 67% before anyone could see it. Reads per…
8 min read
Claude Max subscribers using OpenClaw now pay API rates. Here's the math.
Effective April 4, 2026, Anthropic stopped counting third-party tool usage against Claude subscriptions. OpenClaw got cut first, every other…
7 min read
Microsoft MAI models: what MAI-Transcribe-1, MAI-Voice-1, and MAI-Image-2 actually cost
Three proprietary foundation models from Microsoft's MAI group, released April 2, 2026. MAI-Transcribe-1 matches OpenAI Whisper at…
7 min read
Gemini 3.1 Pro: $2 input, tied for #1 on benchmarks, and 20% cheaper than GPT-5.4
Released February 19, 2026. Costs $2.00/1M input, $12.00/1M output (under 200K tokens). Tied #1 on Artificial Analysis Intelligence Index…
8 min read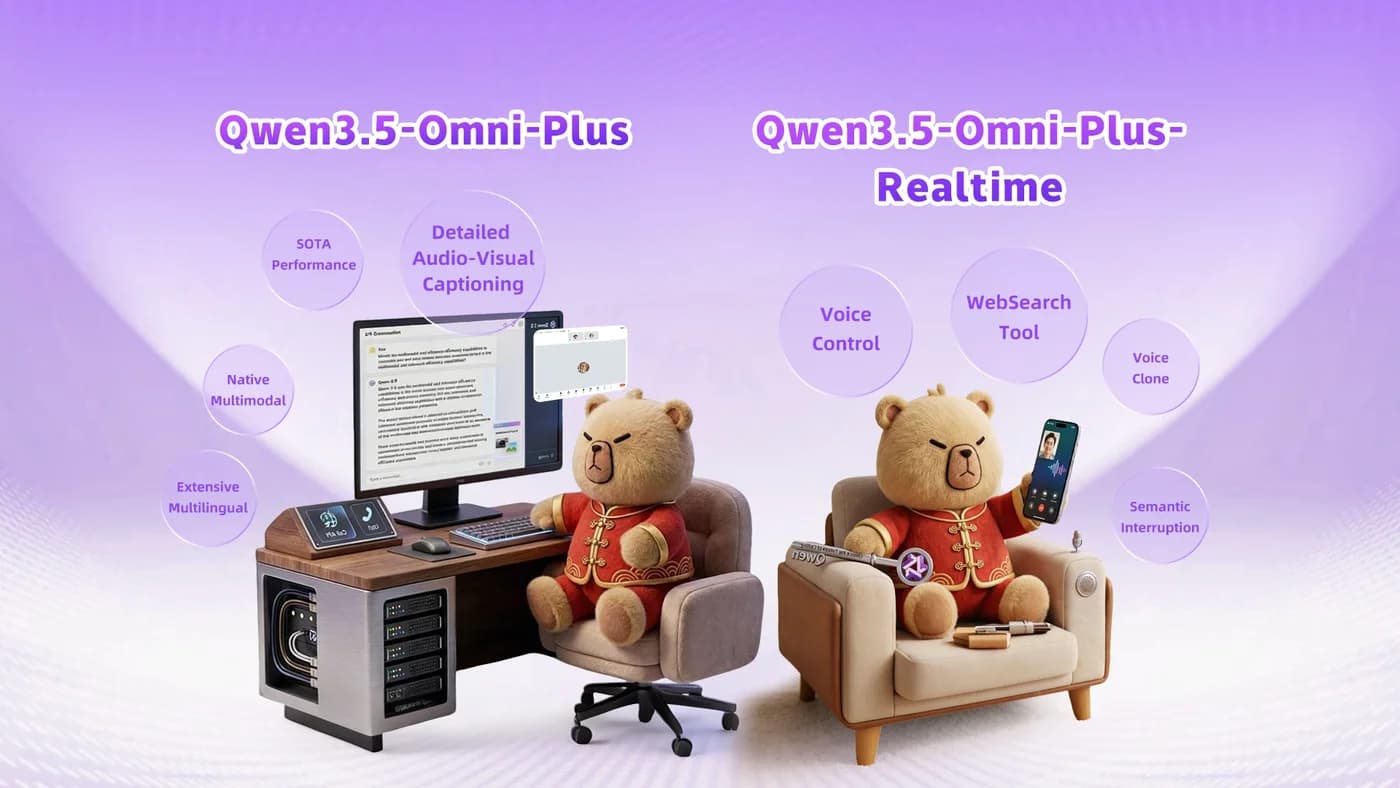
Qwen3.5-Omni: the pricing, the audio benchmarks, and whether the architecture hype is real
Released March 30, 2026. Three variants: Plus (30B-A3B MoE), Flash, Light (open weights). Provisional pricing: Flash at ~$0.065/M input…
7 min read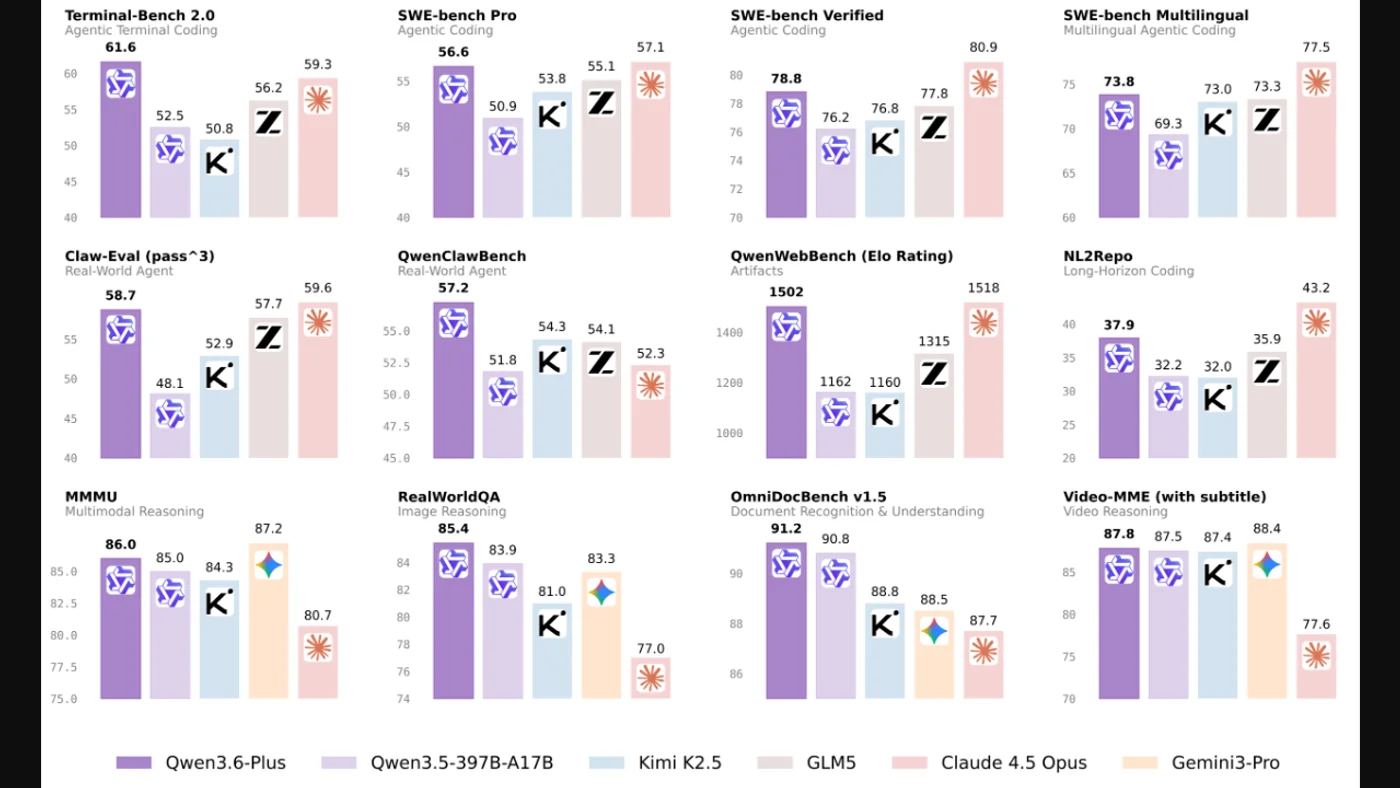
Qwen3.6-Plus: $0.28 per million input tokens, and the benchmark comparison Alibaba chose…
Released April 2, 2026. At $0.276/M input globally, Qwen3.6-Plus costs 18x less than Claude Opus 4.6. It leads on multimodal benchmarks. On…
7 min read
Claude Haiku 3 retires April 19: it's not just a model ID swap
claude-3-haiku-20240307 hits end of life April 19, 2026. Haiku 4.5 is the official replacement at $1.00/$5.00 per million tokens - 4x more…
7 min read
Gemma 4 is out: $0.14 per million tokens for a 31B model scoring 89% on AIME
Google DeepMind released four Gemma 4 models on April 2. The 31B scores 89.2% on AIME 2026 and 84.3% on GPQA Diamond. The 26B MoE variant…
8 min read
Reasoning models in 2026: $0.55 to $20 per million tokens, and when each tier makes sense
DeepSeek R1 costs $0.55 per million input tokens. o3-pro costs $20. On GPQA Diamond, R1 scores 81.0% vs o4-mini's 81.4% - effectively tied…
7 min read
Gemini Flex and Priority inference: how Google's new tiers work and what they cost
Google added Flex and Priority inference to the Gemini API on April 2. Flex gives you batch-level pricing (50% off) with synchronous…
8 min read
Google Gemini API billing caps are live: what developers need to know
As of April 1, 2026, Google enforces mandatory monthly spend caps on all Gemini API billing accounts. Tier 1 hits at $250/month. There is a…
7 min read
OpenAI Deep Research API: what it costs, and why o3-deep-research is 5x pricier than o3
o3-deep-research runs at $10 per million input tokens -- the same base model as o3, which costs $2. You are not paying for a different…
7 min read
OpenAI killed Sora. The math explains why.
$2.1 million in total revenue against $15 million per day in inference costs. A $1 billion Disney deal where no money changed hands. Sora…
9 min read
ARC-AGI-3: the benchmark no AI can crack, and what running it costs
Launched March 25, 2026 at Y Combinator, ARC-AGI-3 is an interactive benchmark with zero instructions -- the AI must figure out the goal…
8 min read
Gemini 2.0 Flash is deprecated: what migration actually costs you
Google deprecated Gemini 2.0 Flash on February 18, 2026, with a June 1 shutdown. The obvious replacement - Gemini 2.5 Flash - is 3x more…
8 min read
Kimi K2.5 vs GPT-5.4: the model Cursor built on, and what it actually costs
Cursor launched Composer 2 without disclosing the base model. A developer intercepted the model ID six hours later -- it was fine-tuned Kimi…
9 min read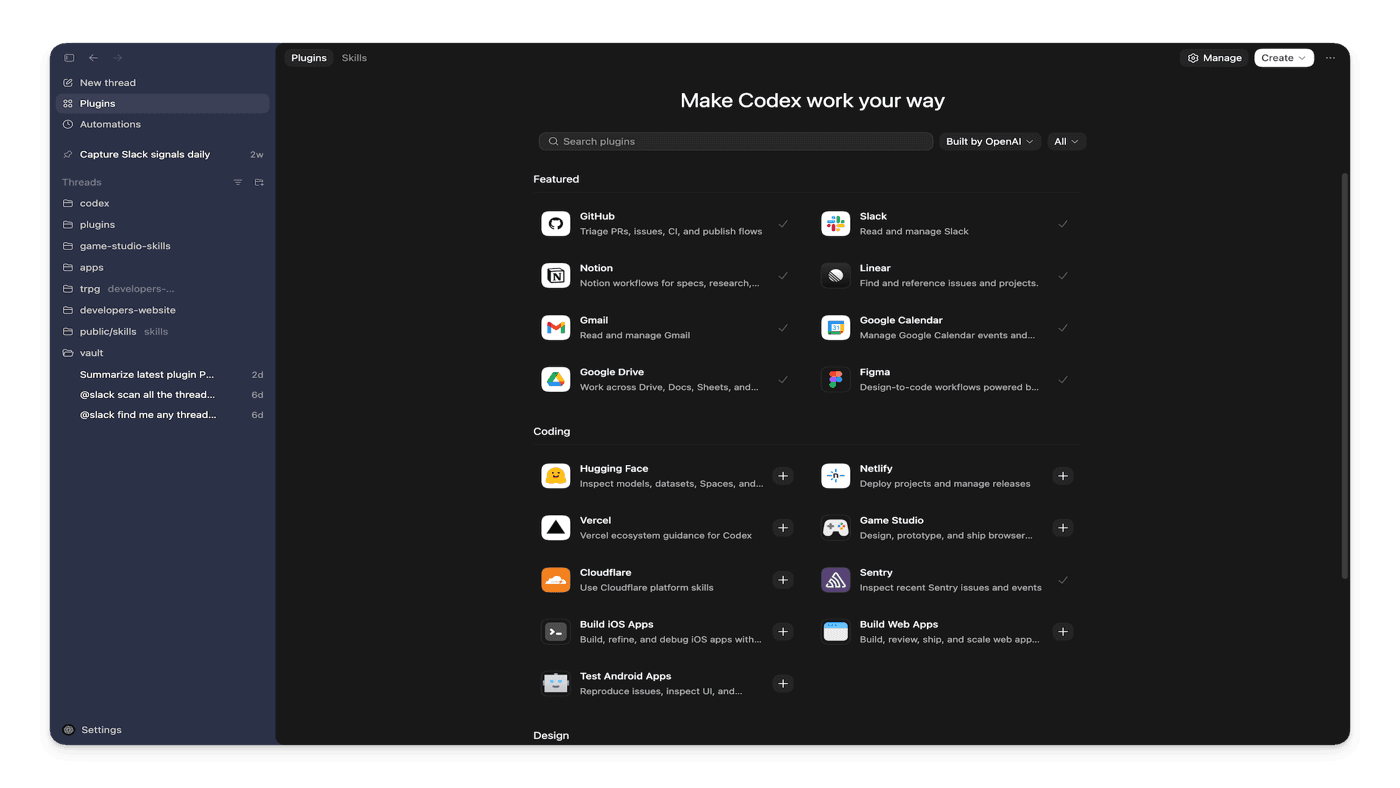
OpenAI Codex pricing: API costs, container billing, and how it stacks up against Claude…
OpenAI Codex runs on gpt-5.2-codex at $1.75/$14.00 per million tokens -- cheaper on input than Claude Sonnet 4.6, roughly equal on output…
8 min read
How much does Claude Code actually cost per session?
Anthropic says the average is $6 per developer per day. Here's what a simple bug fix, a complex feature, and an autonomous computer control…
8 min read
Claude Mythos pricing: what Anthropic's leaked new model will cost developers
Anthropic accidentally exposed internal documents describing Claude Mythos, a new tier above Opus codenamed Capybara. No official pricing…
7 min read
Grok 4.20 Beta: $2 per million tokens, 2M context, and the lowest hallucination rate…
xAI's Grok 4.20 Beta costs $2.00 input / $6.00 output -- cheaper than the Grok 4 it replaces and well below Claude Sonnet 4.6 on output. It…
8 min read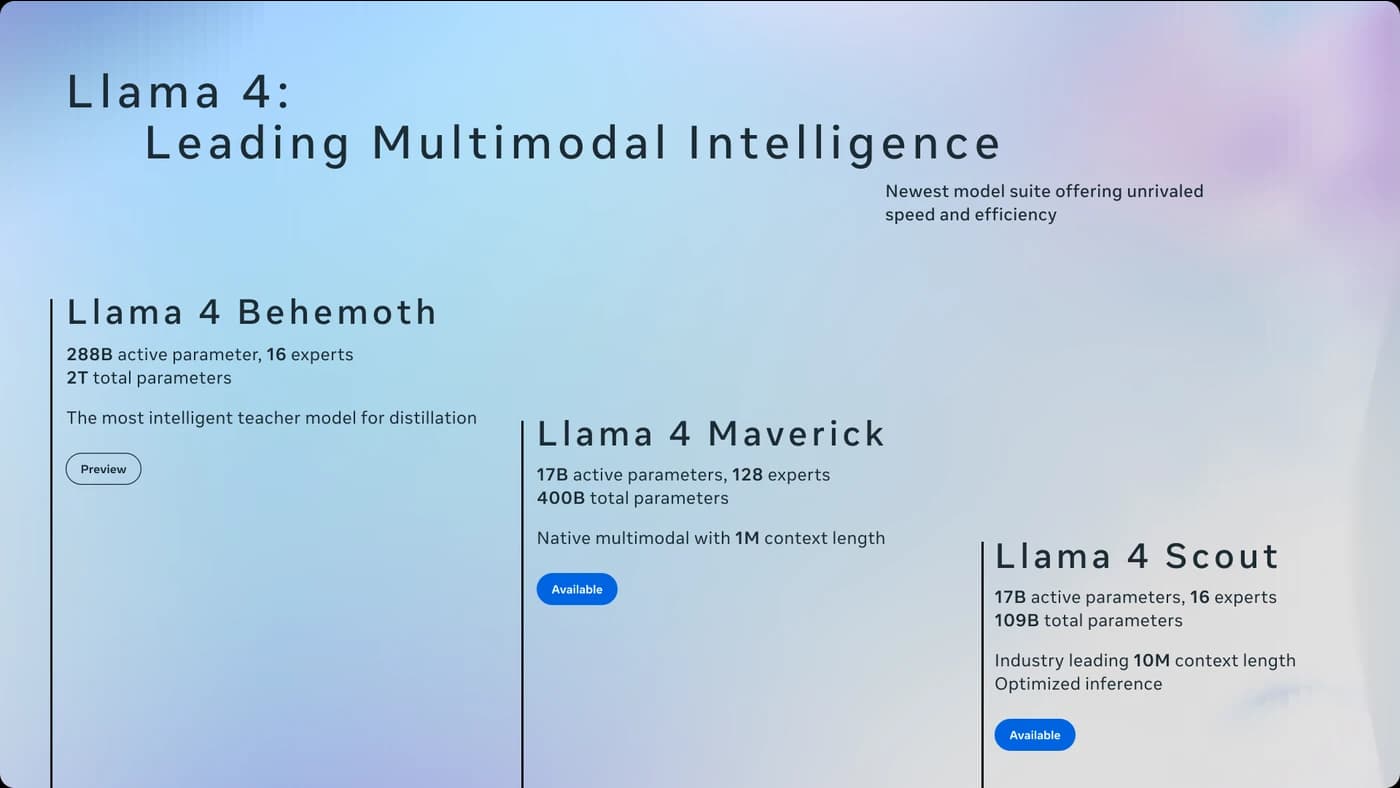
Llama 4 Scout vs Maverick: API pricing, self-hosting costs, and which one to use
Maverick scores 69.8 on GPQA Diamond and costs $0.15 per million input tokens at DeepInfra. Scout has a 10-million-token context window and…
9 min read
DeepSeek V3.2 vs GPT-5.4: Is the 30x price gap worth it?
DeepSeek V3.2 costs $0.28 per million input tokens. GPT-5.4 costs $2.50. We went through the benchmarks, context window caveats, and real…
8 min read
Qwen3.5 Small: the 9B model that beats gpt-oss-120B on four benchmarks
Alibaba released four small models on March 2. The 9B scores 82.5 on MMLU-Pro, ahead of gpt-oss-120B (80.8) and Qwen3-30B (80.9) with 13x…
7 min read
Anthropic drops the 2x long-context surcharge: what Claude now costs at 1M tokens
On March 13, Anthropic removed the pricing penalty that doubled your bill when prompts crossed 200K tokens. Claude Sonnet 4.6 at 1M tokens…
7 min read
Xiaomi MiMo-V2-Pro: the trillion-parameter model that fooled everyone into thinking it was…
For a week, developers thought 'Hunter Alpha' was a stealth DeepSeek V4 leak. It was Xiaomi. MiMo-V2-Pro has 1T+ parameters, scores 78% on…
9 min read
Gemini 3.1 Flash-Lite: $0.25 per million tokens, 1M context, and benchmark scores that…
Google shipped Gemini 3.1 Flash-Lite on March 3 at $0.25/1M input, $1.50/1M output. It scores 86.9% on GPQA Diamond - 14 points ahead of…
8 min read
Mistral Small 4: $0.15 per million input tokens for a multimodal MoE model
Mistral shipped a 119B MoE model that activates only 6.5B parameters per token. It handles text and images, has configurable reasoning, and…
7 min read
GPT-5.4 Mini vs Nano: pricing, benchmarks, and which one to use
OpenAI shipped GPT-5.4 mini ($0.75/1M input) and nano ($0.20/1M input) on March 17. Both are faster than GPT-5 mini but 3-4x pricier. We…
9 min read
Claude 5 release date: what Anthropic has actually said
Anthropic hasn't announced Claude 5. But between Dario Amodei's public statements, their release cadence, and a $30B funding round, we can…
8 min read
How to cut your LLM API bill by 60% without changing models
Five tactics that work with any provider. Prompt caching, batch processing, output optimization, model routing, and semantic caching. We…
10 min read
The AI Price Index: How LLM costs dropped 300x in three years
In March 2023, GPT-4 cost $30 per million input tokens. Today, you can get GPT-4-level quality for under $0.10. We tracked every major price…
12 min read
GLM-5 Turbo: the first model built for OpenClaw. Is it worth $1.20 per million tokens?
Zhipu released a model trained from scratch for OpenClaw agentic workflows. At $1.20/1M input it's 4x pricier than MiniMax M2.5. Here's the…
6 min read
NVIDIA Nemotron 3 Super: Pricing, Benchmarks & What 12B Active Parameters Actually Gets…
NVIDIA dropped a 120B open-source model at GTC that only activates 12B parameters per token. At $0.10/1M input on DeepInfra, it's 25x…
8 min read
Gemini Embedding 2: Pricing, Limits, and How It Compares to OpenAI
Google shipped a multimodal embedding model yesterday. It handles text, images, audio, video, and PDFs in one vector space. Here's the…
6 min read
GPT-6 Release Date: What We Actually Know Right Now
GPT-5.4 just dropped. Naturally, everyone wants to know when GPT-6 is coming. Here's everything OpenAI has actually said, what the timeline…
7 min read
Anthropic Built a Marketplace. No Commission, Complicated Timing.
Anthropic launched the Claude Marketplace for enterprise customers this week. Zero commission, six launch partners, and a Pentagon…
5 min read
OpenAI GPT-5.4: Pricing, Benchmarks & What Developers Actually Need to Know
OpenAI just dropped GPT-5.4 with a 1M+ context window, native computer use, and some serious coding chops. Here's the honest breakdown on…
8 min read
GPT-5.4 vs Claude Opus 4.6 vs Gemini 3.1 Pro: Which One Should You Actually Use?
Three frontier models, three very different trade-offs. We ran through the benchmarks, pricing, and real-world quirks to figure out which…
10 min read